Environment Resolution
When a webhook fires, varTrack resolves a single environment string from the event. This string is used to:
- Resolve
{env}indestination_template - Select the correct subtree from env-keyed config files
- Determine which sink collection, prefix, or path to write to
Resolution order
varTrack tries each strategy in order and uses the first one that produces a match:
| Priority | Strategy | Example |
|---|---|---|
| 1 | branch_map[branch] |
main → production |
| 2 | file_path_map |
production → configs/prod.yaml |
| 3 | pr_as_env: true |
PR #42 → pr-42 |
| 4 | branch_as_env: true |
branch develop → develop |
| 5 | tag_as_env: true |
tag v1.2.3 → v1.2.3 |
| 6 | none | the push feeds no environment of the rule: it is skipped |
There is no default environment. A push that none of the strategies places feeds nothing of the rule, so it is skipped: the task ends Succeeded · nothing to do and says so (branch feature/x feeds no environment of gitea/redis-hash), and nothing is written to an environment nobody declared. vt sync --env X to an environment the rule does not produce is refused the same way (nothing feeds X in the … rule).
A rule must name its environments
A rule has to say where its environments come from: branch_map, file_path_map, branch_as_env, pr_as_env or tag_as_env, in config.cue or the tenant's bundle.json (a repository's vartrack.json may add to them, but cannot be the only place). A rule that names none is refused when it is loaded (so is a rule that names no file to read: it needs file_name or file_path_map in the same two places): nothing runs it, the Rules page lists it as Refused with the reason, an event (RuleRefused) says so, vt validate reports it for a bundle.json, and the rest of the bundle loads.
To keep writing to an environment called default, map a branch to it. The environment, its destinations and its data are the same as before:
default is then an ordinary name: when the branch_map stops mapping it, it is a leftover like any other ("No longer synced by this rule": not compared with Git, its Diff, Sync and Dry run disabled, Forget to drop it).
pr_as_env, branch_as_env and tag_as_env used to be called env_as_pr, env_as_branch and env_as_tags (the S3 option prefix_as_env was env_as_prefix, and ZooKeeper's zk_path_template is now destination_template). The old names still work in config.cue, bundle.json and vartrack.json; varTrack logs a warning with the new name.
branch_map — explicit mapping
Map specific branch names to environment names:
rules: [{
  platform:   "github"
  datasource: "mongo"
  file_name: "app-settings.yaml"
  branch_map: {
    main:    "production"
    develop: "staging"
    qa:      "qa"
  }
}]
Pushes to main write to production-config. Pushes to develop write to staging-config. Any branch not in the map falls through to the next strategy.
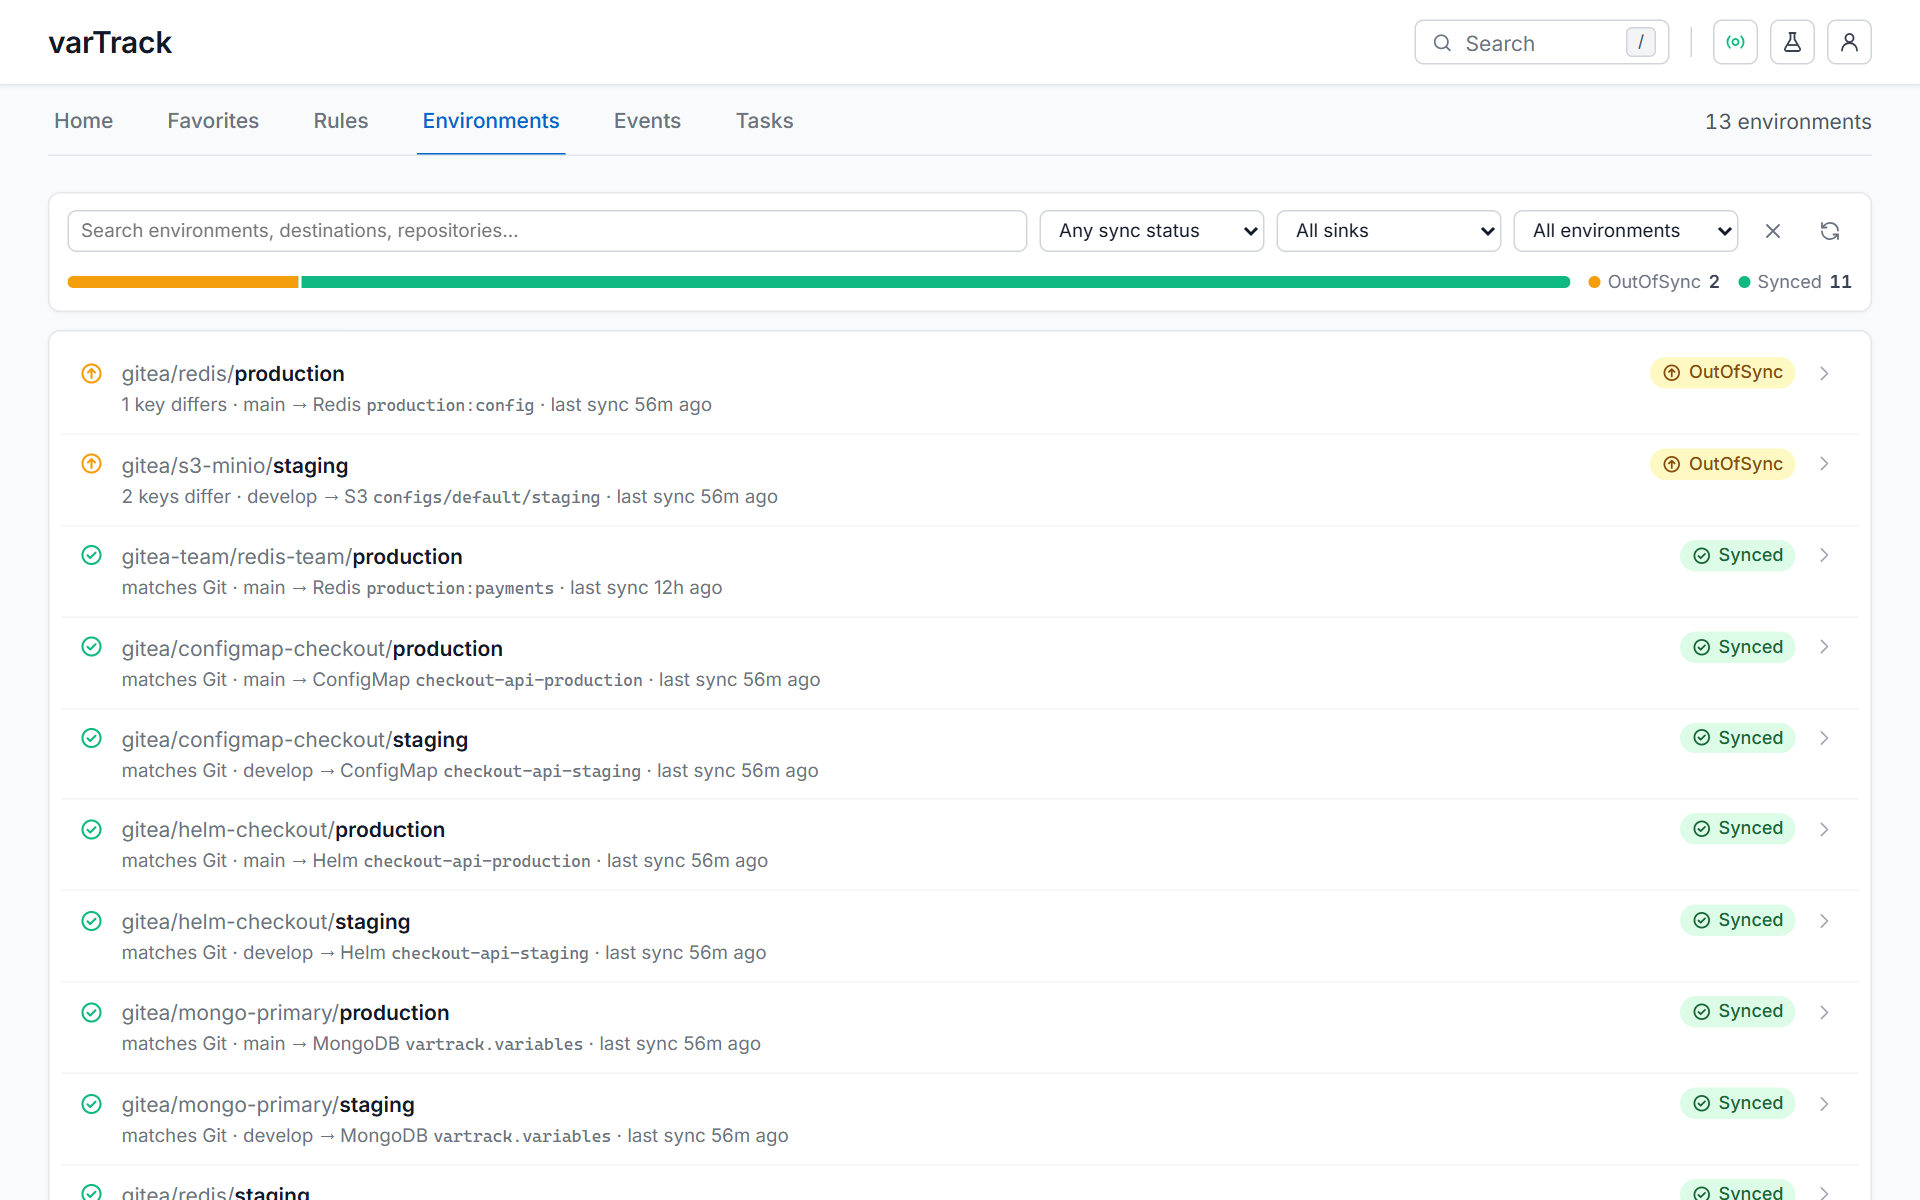
The web UI's Environments page lists every resolved environment with the branch it comes from and where it is written:
file_path_map — one file per environment
Map each environment to the file that holds its settings, as {env: path}:
rules: [{
  platform:   "github"
  datasource: "mongo"
  file_path_map: {
    production: "configs/production.yaml"
    staging:    "configs/staging.yaml"
  }
}]
A push that changes configs/production.yaml resolves to production. The path is the file's exact
path in the repository, not a pattern. The same map says which file to read for an environment when a
sync is started by hand (vt sync --revision, the web UI's Sync). A map written the other way round,
{path: env}, is not read that way: the log says so, and the push resolves by the rules below it.
pr_as_env — PR environments
Pull request events resolve to pr-{number}. Useful for ephemeral preview environments.
branch_as_env — branch name as environment
The branch name becomes the environment name directly:
tag_as_env — tag name as environment
Tag push events use the tag name as the environment:
root_key — extracting a subtree before slicing
If your config file has a wrapper key, set root_key in the rule to unwrap it first. varTrack extracts the subtree under that key, then runs env auto-detection on it.
# configs/app.yaml
vartrack:
  production:
    database_host: mongo.prod.internal
  staging:
    database_host: mongo.staging.internal
other_tool:
  setting: ignored      # not under root_key — never touched
root_key: "vartrack" → extracts the inner dict → Pattern 1 runs on it → database_host=mongo.prod.internal for production.
Set root_key: "" to always process the whole file regardless of structure.
If the key doesn't exist in the file, varTrack soft-falls back to the whole file.
Auto-detection from config file structure
When your config file itself is keyed by environment, varTrack auto-detects the structure and extracts only the relevant slice — no extra rule config needed. Three patterns are supported.
Pattern 1 — all top-level keys are env names
Every top-level value is a dict. varTrack merges default first, then the matching env overrides it.
# configs/app.yaml
production:
  database_host: mongo.prod.internal
  max_connections: 100
staging:
  database_host: mongo.staging.internal
  max_connections: 10
default:
  max_connections: 5    # fallback for unknown envs
  log_level: info
| env | result |
|---|---|
production |
database_host=mongo.prod.internal, max_connections=100, log_level=info |
staging |
database_host=mongo.staging.internal, max_connections=10, log_level=info |
pr-42 |
max_connections=5, log_level=info (from default) |
Pattern 2 — per-field env sub-keys mixed with scalars
Each field that varies per env has a dict of env→value. Fields that are the same across all envs are plain scalars.
# configs/app.yaml
database_host:
  production: mongo.prod.internal
  staging:    mongo.staging.internal
  default:    mongo.local
max_connections: 50     # same for every env — written as-is
log_level: info
| env | result |
|---|---|
production |
database_host=mongo.prod.internal, max_connections=50, log_level=info |
staging |
database_host=mongo.staging.internal, max_connections=50, log_level=info |
pr-42 |
database_host=mongo.local, max_connections=50, log_level=info |
Pattern 3 — env dicts and scalar defaults at the same level
Some keys at the same nesting level are env names (dicts with overrides), others are plain scalars that apply to every env. Order in the file doesn't matter — varTrack categorizes by value type, not position. The env dict is merged on top of the scalars.
{
    "production": { "name": "worn",  "db": "mongo.prod.internal" },
    "predev":     { "name": "dan",   "db": "mongo.dev.internal"  },
    "name":       "bob",
    "age":        33,
    "timeout":    30
}
| env | result |
|---|---|
production |
name=worn, db=mongo.prod.internal, age=33, timeout=30 |
predev |
name=dan, db=mongo.dev.internal, age=33, timeout=30 |
unknown (no match, no default dict) |
data returned unchanged |
Add a default dict to handle unknown envs:
unknown env → name=bob, age=33.
Pattern 3 — env-named top-level dicts mixed with scalar defaults
Top-level dicts whose key matches the resolved env are applied as overrides. Top-level scalars are universal defaults merged underneath:
| env | result |
|---|---|
prod |
name=worn, age=33 |
predev |
name=dan, age=33 |
unknown (no matching dict, no default dict) |
data returned unchanged |
You can also include a default dict for unknown env fallback:
unknown env → name=bob, age=33.
default fallback
In all three patterns, if the resolved env has no matching key, varTrack silently falls back to the default key. If there is no default either, the data is returned unchanged. This default is a key inside the file, not an environment: which environment a push feeds is decided above, and there is no default environment.
root_key — extracting a subtree before slicing
Real config files often live alongside other tooling config (Spring, Maven, npm, etc.). Use root_key to extract only the varTrack-relevant subtree before env-detection runs.
Set root_key: "" to always process the whole file. If the key doesn't exist, varTrack soft-falls back to the whole file.
Example — package.json
A Node.js project that also carries deploy config inside package.json:
{
  "name": "my-app",
  "version": "1.0.0",
  "scripts": { "start": "node index.js" },
  "vartrack": {
    "production": { "API_URL": "https://api.prod.com",  "LOG_LEVEL": "warn"  },
    "staging":    { "API_URL": "https://api.stg.com",   "LOG_LEVEL": "info"  },
    "default":    { "API_URL": "https://api.local.com", "LOG_LEVEL": "debug" }
  }
}
rules: [{
  file_name: "package.json"
  root_key:  "vartrack"       // ignore name/version/scripts — only sync vartrack block
  branch_map: { main: "production", develop: "staging" }
}]
Push to main → API_URL=https://api.prod.com, LOG_LEVEL=warn written to the sink.
Example — pom.xml (Maven)
A Java project with deploy properties in pom.xml. varTrack parses XML and extracts the subtree:
<project>
  <groupId>com.example</groupId>
  <artifactId>my-service</artifactId>

  <vartrack>
    <production>
      <database_host>mongo.prod.internal</database_host>
      <max_connections>100</max_connections>
    </production>
    <staging>
      <database_host>mongo.staging.internal</database_host>
      <max_connections>10</max_connections>
    </staging>
    <default>
      <max_connections>5</max_connections>
    </default>
  </vartrack>
</project>
rules: [{
  file_name: "pom.xml"
  root_key:  "vartrack"
  branch_map: { main: "production", develop: "staging" }
}]
Push to main → database_host=mongo.prod.internal, max_connections=100.
Combining strategies
Strategies can be combined. varTrack uses the first one that matches:
rules: [{
  platform:   "github"
  datasource: "mongo"
  file_name: "app-settings.yaml"
  branch_map: {
    main:    "production"   // explicit — highest priority
    develop: "staging"
  }
  pr_as_env:     true       // fallback for PRs not in branch_map
  branch_as_env: true       // fallback for all other branches
}]
| Event | Resolved env |
|---|---|
Push to main |
production (from branch_map) |
Push to develop |
staging (from branch_map) |
| PR #42 opened | pr-42 (from pr_as_env) |
Push to feature/x |
feature/x (from branch_as_env) |